Movies (vega-datasets) dataset
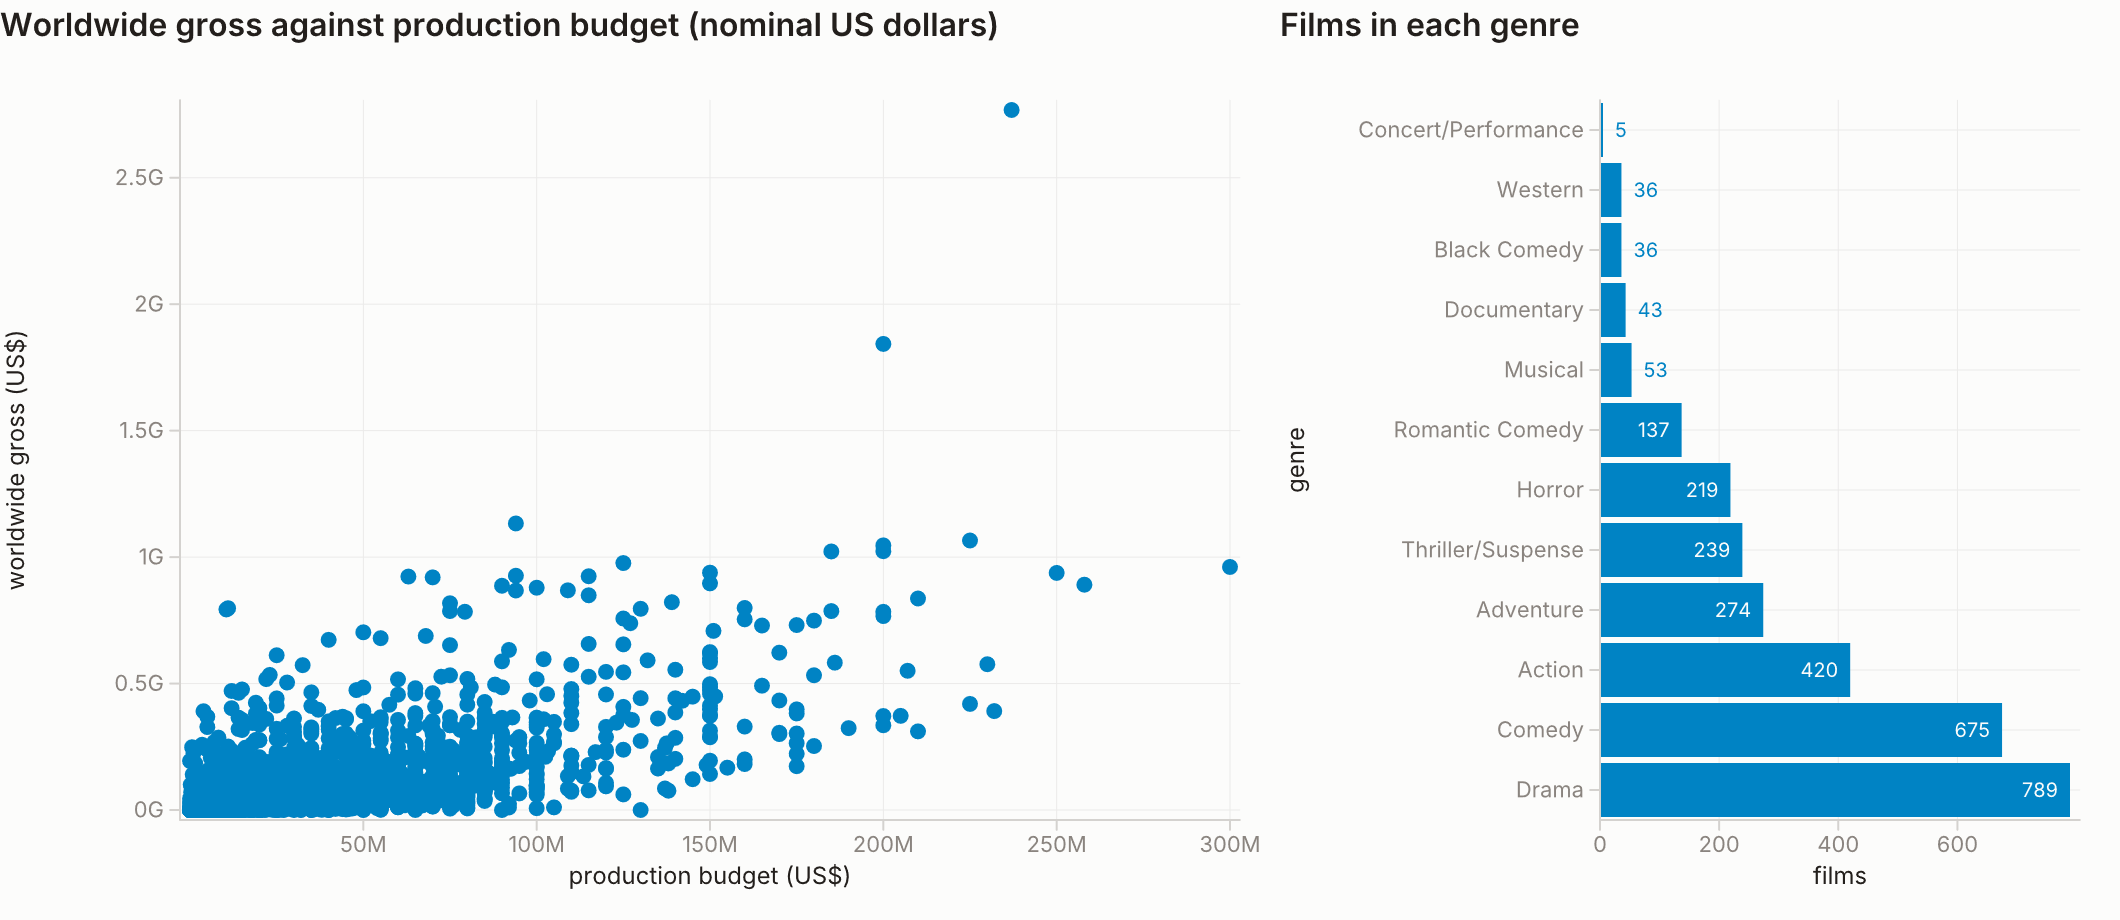
3,201 films from vega-datasets, with production budget, US and worldwide gross, DVD sales, running time, distributor, director, genre and two critic scores. Budgets and grosses are in nominal US dollars, not adjusted for inflation. Release dates arrive as strings like 'Jun 12 1998' and are read as dates, and nine titles are bare numbers, such as 1776 and 300, which vega-datasets keeps on purpose as a data-quality feature.
Load it
These commands install arc, Meridian’s open-source Protocol runner, clone the open-analytics repository and run this Protocol, which writes build/movies.parquet in open-analytics/examples/movies.
curl -fsSL https://install.meridian.online/arc | bash
git clone https://github.com/meridian-online/open-analytics
cd open-analytics/examples/movies && arc run
arc runs the Protocol’s SQL on DuckDB 2.x, which its installer puts in place when no DuckDB is on your PATH, saying what to add to PATH; the last step, which describes the Parquet, needs finetype 0.6.54 or later on your PATH.
Columns
| Name | Type | Description |
|---|---|---|
| title | string | Film title. Nine of the 3,201 are bare JSON numbers rather than strings — 1776, 2012, 300 and their kind — which is why the source column arrives JSON-typed; vega-datasets documents this as a deliberate data-quality feature of the dataset. |
| release_date | date | US release date, parsed from the source's 'Jun 12 1998' strings. All 3,201 parsed at the time this Protocol was written. |
| mpaa_rating | string | MPAA certificate, as the source spells it. |
| major_genre | string | Single genre label assigned by the source. |
| creative_type | string | Source's commercial categorisation, e.g. Contemporary Fiction, Super Hero. |
| source_material | string | What the film was adapted from, if anything — the source's 'Source' column, renamed so it does not collide with the descriptor's own 'sources'. |
| distributor | string | Theatrical distributor. |
| director | string | Director, where the source records one. |
| running_time_min | integer | Running time in minutes. |
| production_budget | integer | Production budget in nominal US dollars, not inflation-adjusted. |
| us_gross | integer | US theatrical gross in nominal US dollars. |
| worldwide_gross | integer | Worldwide theatrical gross in nominal US dollars. |
| us_dvd_sales | integer | US DVD sales in nominal US dollars; absent for most rows. |
| imdb_rating | number | IMDB user rating out of 10, as captured by the source at collection time. |
| imdb_votes | integer | Number of IMDB votes behind that rating. |
| rotten_tomatoes_rating | integer | Rotten Tomatoes score out of 100, as captured by the source at collection time. |
Source and licence
Licence
Sources
Meridian hosts none of this data: the Protocol downloads it, from the address its fetch step names, when you run it.
The steps
4 stepsduckdb >=1.2Every step runs in order. op: steps are typed, versioned operators; sql: steps are DuckDB models.
- 01fetch_moviesop: http_fetch@1
Fetch movies.json from vega-datasets 3.2.1, pinned by sha256.
producesbuild/movies.jsonwithurl: https://cdn.jsdelivr.net/npm/vega-datasets@3.2.1/data/movies.json out: build/movies.json sha256: e63c499759e3b07b49563e036f55290f87feb56def8703ec049ca305ab1523d3 headers: User-Agent: Meridian Protocol (open-analytics demo; research@meridian.online) - 02loadsql: models/load.sql
Take each title out of the column's mixed JSON type, parse release dates such as 'Jun 12 1998' into dates, and rename the columns to snake_case.
readsbuild/movies.jsonproducesmoviesmodelmodels/load.sql - 03export_moviesop: parquet_export@1
Write build/movies.parquet, on your own disk. ORDER BY ALL makes the bytes reproducible: the only rows it leaves unordered are exact duplicates of each other, which cannot change the output.
readsmoviesproducesbuild/movies.parquetwithinput: movies dest: build/movies.parquet compression: zstd order_by: ALL - 04describeop: datapackage_describe@1
Emit datapackage.json from the built Parquet: finetype types every column, and descriptor.overrides.json adds the curated title, licence, sources and per-field prose.
readsbuild/movies.parquetdescriptor.overrides.jsonproducesdatapackage.jsonwithparquet: build/movies.parquet overrides: descriptor.overrides.json out: datapackage.json