MedMCQA dataset
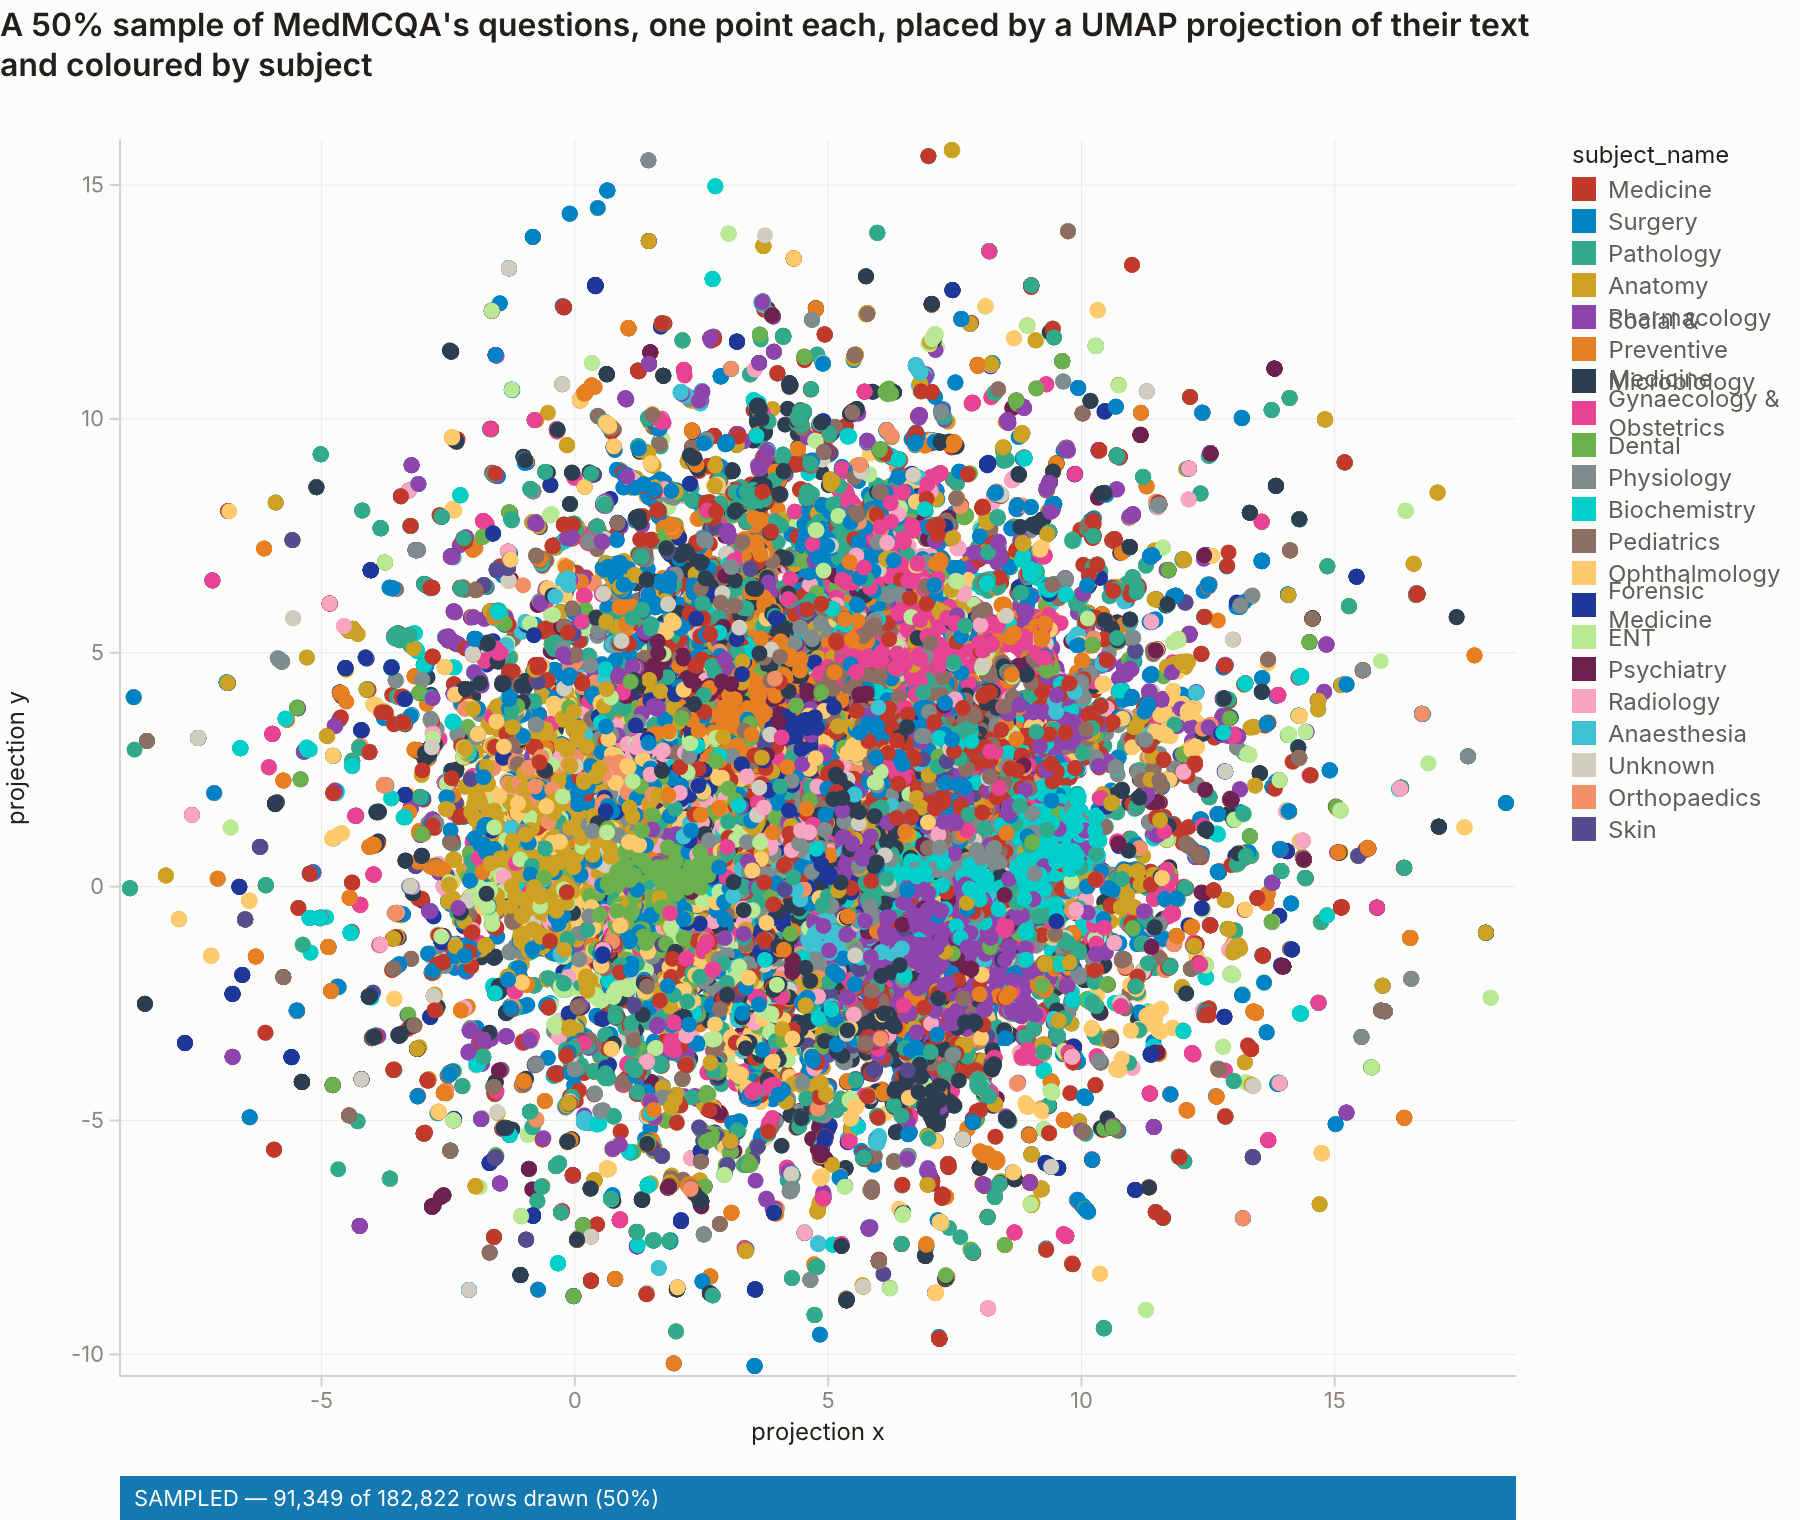
MedMCQA is a set of multiple-choice questions from medical entrance exams, published by Pal, Umapathi and Sankarasubbu at CHIL 2022. The recipe reads the source's train split, 182,822 questions, each with its four options, the correct one, an explanation where the source gives one, and the subject and topic it was filed under. It also places each question on a two-dimensional map by what its text is about (an embedding of the text, reduced with UMAP); read the map as regions of related questions, not as distances. No licence is asserted: the source's own pages disagree about its terms, so treat what you build from it as unlicensed third-party content.
Load it
These commands install arc, Meridian’s open-source Protocol runner, clone the open-analytics repository and run this Protocol, which writes build/medmcqa.parquet in open-analytics/examples/medmcqa.
curl -fsSL https://install.meridian.online/arc | bash
git clone https://github.com/meridian-online/open-analytics
cd open-analytics/examples/medmcqa && arc run
arc runs the Protocol’s SQL on DuckDB 2.x, which its installer puts in place when no DuckDB is on your PATH, saying what to add to PATH; the last step, which describes the Parquet, needs finetype 0.6.54 or later on your PATH.
This Protocol needs a DuckDB embedding extension on disk before it will run; its README says how to build it and where to put it.
Columns
| Name | Type | Description |
|---|---|---|
| id | string | The source's own UUID for the question. Distinct on all 182,822 rows, which is what makes this Protocol's ORDER BY ALL export a total order. models/load.sql stops the run if it ever stops being distinct. |
| question | string | The question text. THIS is the column that was embedded and projected — the Embedding Atlas gallery's own generator for this dataset names it, as SELECT row_number() OVER () AS id, question AS text FROM data_frame. |
| opa | string | Answer option A, under the source's own abbreviated name. |
| opb | string | Answer option B, under the source's own abbreviated name. |
| opc | string | Answer option C, under the source's own abbreviated name. |
| opd | string | Answer option D, under the source's own abbreviated name. |
| cop | integer | Correct option: 0-based index into opa/opb/opc/opd, as the source records it. Meaningless on its own without the four option columns — read answer_text instead. The source's test split sets this to -1 on every row; this Protocol builds train, where it is 0-3, and models/load.sql stops the run if a value outside 0-3 ever appears. |
| choice_type | string | Whether the source filed the question as single or multi. 120,765 of these 182,822 rows are single and 62,057 are multi. |
| exp | string | The source's worked explanation of the correct answer, under its own abbreviated name. NULL on 21,953 of these 182,822 rows, and left NULL rather than blanked: no explanation and an empty explanation are different facts. |
| subject_name | string | The medical subject the question was filed under — 21 distinct values across these rows. |
| topic_name | string | A finer label within the subject. NULL on 95,613 of these 182,822 rows, and left NULL. |
| projection_x | number | The first UMAP coordinate of this row's question text. A position on a map, not a measurement: read the map as regions. See the package description. |
| projection_y | number | The second UMAP coordinate of this row's question text. Read with projection_x and only against rows sharing this row's projection_fit_id. |
| projection_fit_id | string | A fingerprint of the exact feature matrix and knobs the UMAP fit consumed, the same value on every row. Two exports carrying the same value came from one fit and their coordinates are comparable; two carrying different values are two maps, and a position in one says nothing about a position in the other. |
| answer_text | string | The text of the correct option, joined here from cop so a reader does not have to index the four option columns by hand. |
Source and licence
Licence
- No licence declared at source. No licence is asserted for this data. The mirror's YAML tag says apache-2.0, the same card's Licensing Information section says '[Needs More Information]', and the authors' code repository is MIT over code that ships no data. A repository tag is not the licensor and a code licence is not a data grant, so all three are recorded and none is relied on. Nothing here is redistributed.
Sources
- openlifescienceai/medmcqa on Hugging Face, revision 91c6572c (train split)
- MedMCQA — Pal, Umapathi and Sankarasubbu, "MedMCQA: A Large-scale Multi-Subject Multi-Choice Dataset for Medical domain Question Answering", CHIL 2022 (licensor)
- minishlab/potion-base-8M — the static embedding model whose vectors projection_x and projection_y are a UMAP reduction of, embedded in and applied by the staticembed DuckDB extension
Meridian hosts none of this data: the Protocol downloads it, from the address its fetch step names, when you run it.
The steps
6 stepsduckdb >=1.2Every step runs in order. op: steps are typed, versioned operators; sql: steps are DuckDB models.
- 01fetch_medmcqaop: http_fetch@1
Fetch the train split's Parquet from the openlifescienceai/medmcqa repository on Hugging Face, pinned to a commit revision and by sha256.
producesbuild/medmcqa.src.parquetwithurl: https://huggingface.co/datasets/openlifescienceai/medmcqa/resolve/91c6572c454088bf71b679ad90aa8dffcd0d5868/data/train-00000-of-00001.parquet out: build/medmcqa.src.parquet sha256: b119434ba551517a6ec0ba1f7e0b4c029165ed284a4704f262ce37c791c493c5 headers: User-Agent: Meridian Protocol (open-analytics demo; research@meridian.online) - 02embed_questionsop: text_embed@1
Embed each question's text with a static sentence embedder (the staticembed DuckDB extension), one 256-dimensional vector per question.
readsbuild/medmcqa.src.parquetvendor/staticembed.duckdb_extensionproducesbuild/medmcqa.embedded.parquetwithinput: build/medmcqa.src.parquet text_column: question extension: vendor/staticembed.duckdb_extension out: build/medmcqa.embedded.parquet vector_column: embeddingneeds the staticembed DuckDB extension at vendor/staticembed.duckdb_extension, which has no published URL; absent, the run stops at once naming the file. The Protocol's README says how to build it.
- 03project_questionsop: umap_project@1
Reduce the vectors to two map coordinates, projection_x and projection_y, with UMAP over cosine distance. The seed is frozen and the work single-threaded, so two runs land on the same map. Read it as regions, not distances.
readsbuild/medmcqa.embedded.parquetproducesbuild/medmcqa.projected.parquetwithinput: build/medmcqa.embedded.parquet columns: [embedding] out: build/medmcqa.projected.parquet metric: cosine - 04loadsql: models/load.sql
Drop the vectors, keep the two coordinates and the fit's fingerprint, and join the correct option's text in as answer_text. Stops the run if the answers are withheld or any id repeats.
readsbuild/medmcqa.projected.parquetproducesmedmcqamodelmodels/load.sql - 05export_medmcqaop: parquet_export@1
Write build/medmcqa.parquet, on your own disk. ORDER BY ALL is a total order here, since every id is distinct, so the bytes reproduce.
readsmedmcqaproducesbuild/medmcqa.parquetwithinput: medmcqa dest: build/medmcqa.parquet compression: zstd order_by: ALL - 06describeop: datapackage_describe@1
Emit datapackage.json from the built Parquet: finetype types every column, and descriptor.overrides.json adds the curated title, licence, sources and per-field prose.
readsbuild/medmcqa.parquetdescriptor.overrides.jsonproducesdatapackage.jsonwithparquet: build/medmcqa.parquet overrides: descriptor.overrides.json out: datapackage.json