Census Income (Adult) dataset
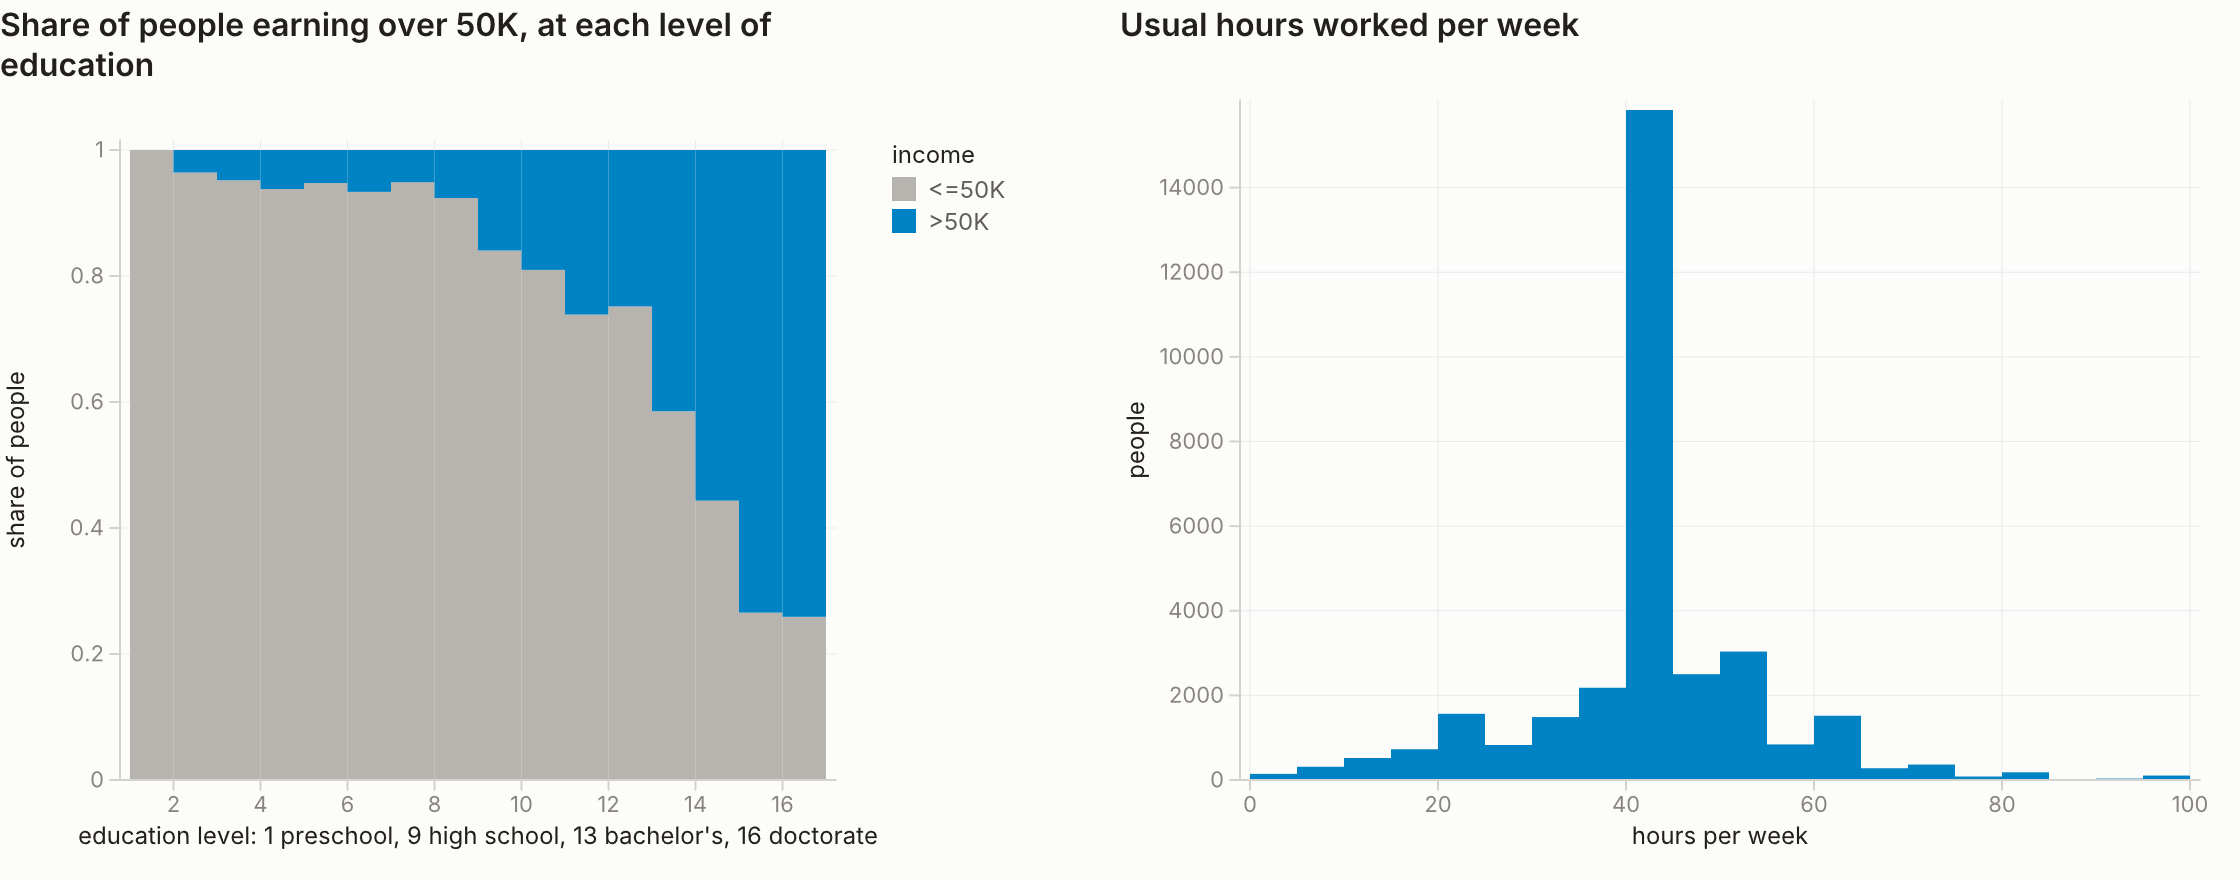
The standard 'Adult' benchmark extract of the 1994 US Census: 32,561 person records with demographic and employment attributes and an income label, '<=50K' or '>50K'. The recipe reads it from the UCI Machine Learning Repository, which publishes it under CC BY 4.0 with credit to Becker and Kohavi (1996). The recipe treats it as a shape of data, not as a source of fact about anyone; its columns use that census's own categories.
Load it
These commands install arc, Meridian’s open-source Protocol runner, clone the open-analytics repository and run this Protocol, which writes build/census_income.parquet in open-analytics/examples/census-income.
curl -fsSL https://install.meridian.online/arc | bash
git clone https://github.com/meridian-online/open-analytics
cd open-analytics/examples/census-income && arc run
arc runs the Protocol’s SQL on DuckDB 2.x, which its installer puts in place when no DuckDB is on your PATH, saying what to add to PATH; the last step, which describes the Parquet, needs finetype 0.6.54 or later on your PATH.
Columns
| Name | Type | Description |
|---|---|---|
| age | integer | Age in years. |
| workclass | string | Employment sector. The source's '?' placeholder is NULL here — 1,836 rows. |
| final_weight | number | Census sampling weight ('fnlwgt'): how many people in the population this record is taken to represent. Not a property of the person. |
| education | string | Highest education level reached, as a label. |
| education_num | integer | The same education level as an ordinal number, so it can be compared. |
| marital_status | string | Marital status as the 1994 Census coded it. |
| occupation | string | Occupation category. The source's '?' placeholder is NULL here — 1,843 rows. |
| relationship | string | Role within the household, as the 1994 Census coded it. |
| race | string | Race as recorded by the 1994 US Census, using that instrument's categories. |
| sex | string | Sex as recorded by the 1994 US Census, which offered two values. |
| capital_gain | integer | Capital gains in nominal 1994 US dollars; zero for most rows. |
| capital_loss | integer | Capital losses in nominal 1994 US dollars; zero for most rows. |
| hours_per_week | integer | Usual hours worked per week. |
| native_country | string | Country of origin. The source's '?' placeholder is NULL here — 583 rows. |
| income | string | The benchmark's label, kept as the source's own '<=50K' / '>50K' strings rather than folded to a boolean. |
Source and licence
Licence
Sources
Meridian hosts none of this data: the Protocol downloads it, from the address its fetch step names, when you run it.
The steps
4 stepsduckdb >=1.2Every step runs in order. op: steps are typed, versioned operators; sql: steps are DuckDB models.
- 01fetch_adultop: http_fetch@1
Fetch adult.data from the UCI Machine Learning Repository, pinned by sha256. UCI has no revisions, so the hash is the only record of which bytes the recipe was written against.
producesbuild/adult.datawithurl: https://archive.ics.uci.edu/ml/machine-learning-databases/adult/adult.data out: build/adult.data sha256: 5b00264637dbfec36bdeaab5676b0b309ff9eb788d63554ca0a249491c86603d headers: User-Agent: Meridian Protocol (open-analytics demo; research@meridian.online) - 02loadsql: models/load.sql
Read the headerless, comma-separated file under UCI's column names, renamed to snake_case, and turn the source's '?' placeholder into NULL in workclass, occupation and native_country.
readsbuild/adult.dataproducescensus_incomemodelmodels/load.sql - 03export_census_incomeop: parquet_export@1
Write build/census_income.parquet, on your own disk. ORDER BY ALL makes the bytes reproducible: the only rows it leaves unordered are exact duplicates of each other, which cannot change the output.
readscensus_incomeproducesbuild/census_income.parquetwithinput: census_income dest: build/census_income.parquet compression: zstd order_by: ALL - 04describeop: datapackage_describe@1
Emit datapackage.json from the built Parquet: finetype types every column, and descriptor.overrides.json adds the curated title, licence, sources and per-field prose.
readsbuild/census_income.parquetdescriptor.overrides.jsonproducesdatapackage.jsonwithparquet: build/census_income.parquet overrides: descriptor.overrides.json out: datapackage.json